Strategic Insights From Our EKS Modernization Fireside Chat
EKS migrations typically fail on sequencing, as well as the order in which platform work, cost governance, and when cutover decisions happen. Our CEO Stephen Koza raised the problem directly during a recent fireside chat on EKS modernization and what to do first, hosted alongside Mike Connors, EverOps' Director of Agentic Services.
“We're modernizing on AWS, but nobody agrees on what order we should do it in.” - Stephen Koza
Most teams in this position are already running on AWS, and their environments grew independently, each with its own patterns and its own definition of good, which is the same gap we cover in a previous post: Modernization Without Disruption.
This is becoming a frequent conversation happening inside engineering orgs everywhere. Leadership knows containers and EKS are the right direction. What stays unclear is the sequence, specifically what should get done first, what breaks if the order is wrong, and what to do about the bill that shows up six months later for a decision nobody remembers making.
Modernizing now means consolidating all of that into a single paved road that every workload can migrate onto and develop against, so cost, consistency, and architectural decisions happen once instead of differently in every environment. It's the same category of migration behind the Life360 EKS migration our team completed in just six months.
Read on as we break down the sequencing logic behind the session, the cost blind spots, the ownership questions that came up in that conversation, and reveal the same decisions leadership teams everywhere are working through right now.
When you're ready to go deeper, access the full 20-minute conversation EKS Modernization: What Do You Do First?, built for CTOs, VPs of Engineering, and Directors of Platform/Infrastructure accountable for making a Kubernetes modernization hold up in production.
Sequencing Is Not About Being Right
Most teams sequence by business priority or let workload teams volunteer for who goes first. Connors' take is that both put the hardest service first, before the platform has learned anything about itself.
"There's no amount of upfront planning that survives the first few real workloads," Connors states. "So the goal of sequencing is not really to be right. It's just to be wrong cheaply."
That means building in guardrails from the start:
- Place the least critical services first
- Contain the blast radius wherever possible
- Build a platform that can absorb a bad assumption without taking a revenue-generating service down with it
Scoring each workload matters here, capturing blast radius, statefulness, dependency depth, pipeline maturity, and which AWS services it touches. EverOps scores the worst case per dimension, not just the average, since a service that looks fine across four categories and fails one still gets blocked by that one.
Every early migration feeds the next. A team finds a gap, fixes the paved road, and the next workload inherits the fix. Scoring a full catalog by hand collapses under its own weight, which is why most programs abandon the rubric and drift back to letting volunteers decide. However, AI changes that math, making full-depth scoring affordable at scale and keeping the sequencing decision grounded.
The Delay Nobody Sees Coming
When asked what causes the most common unforced, self-inflicted delay when standing up a new EKS platform, Connors pointed to foundational platform capabilities. In other words, how a team gets access to a cluster, how workloads get AWS permissions, how secrets arrive, and what network address space is actually available.
"Foundations in general are not features...Nobody really files the ticket for the identity model." Because nobody files that ticket, the foundational work slides behind the features service teams are actively asking for, and every service in the queue eventually gets blocked by it.
EverOps combats this by mapping platform dependencies before building the onboarding roadmap, and it moves anything multiple services depend on to the front of that roadmap, regardless of what those services are requesting.
That’s not all. The second most common delay is choosing the AWS pattern a team is already comfortable with over the pattern AWS currently recommends. Cluster access and workload identity both have newer approaches, IRSA and Pod Identity among them, that eliminate entire categories of manual coordination.
Sticking with the familiar path quietly costs more over time, and the gap widens as the environment grows more complex. Connors summed up why this keeps happening, stating that, "It really puts a lens on the fact that the engineering activity itself is only part of the situation. The culture, the processes, and the people behind it are just as important."
Why Gradual Cutover Isn't a One-Size-Fits-All Playbook
"Having a gradual cutover playbook applied as a default is definitely something to steer away from," Connors states.
It is the standard move for a reason. Migrating and shifting traffic service by service gives a team a stopping point to revert to if something goes wrong, but it does not work the same way for every kind of service.
Three questions determine which cutover model applies to a given workload:
- Does it hold state?
- Does it already have an operating or maintenance window the team can work within?
- Does it span AWS availability zones or regions?
A stateless service can take an incremental traffic shift over time, with short-lived session state pinned or drained from the previous environment before the cut. A stateful service, player data being one example from a client engagement, is considerably more nuanced, and the right approach depends on exactly how that state is maintained.
The mistake most teams make is trying to apply one cutover model across every workload, when the right approach has to flex with how each workload is actually built.
Where the Cost Actually Shows Up
Cost is on every client's mind going into a modernization, and it tends to show up where teams don't expect it. "The number one way is traffic topology," Connors said. "Not that it's the most expensive thing, but it's something that's rarely accounted for." It rarely appears on a dashboard or in the conversations an organization is already having about spending.
By default, EKS treats every healthy pod as an equally good destination for a request, regardless of where that request originated. A meaningful share of internal traffic crosses availability zone boundaries and gets billed in both directions while old and new environments run in parallel during migration. Ingress, egress, and NAT gateway routing all carry cost implications that are easy to overlook until the bill arrives.
FinOps tooling is also high up on almost every client's day-one list. It works only once governance is in place first. EKS schedules workloads based on what teams request, not what they actually use, so over-provisioning becomes the default.
Fixing that is a policy decision, and it has to come first. Purchase commitments come after, since most modernizations end up locking in multi-year commitments against an unoptimized baseline otherwise. Either way, getting the policy right first cuts that cost in weeks instead of months.
The Ownership Problem That Always Surfaces Last
Ownership is the piece that shows up last in platform engineering and matters the most. A consolidation effort exposes it almost immediately. Different teams end up owning the same function across environments, resolved differently, often undocumented, and sometimes with conflicting versions of the same policy.
The platform's job is to define that baseline up front, sorting out what the platform owns, what the workload owns, and what each service brings. The baseline holds steady while the paved road it describes keeps evolving, absorbing fixes as new workloads move through it. Defining that baseline makes the platform's failure domain genuinely finite.
A workload that won't start almost always traces back to one of a handful of causes like an image issue, an admission policy, or a secret path. None of those show up on a typical service dashboard. "Those bounded problems are addressable even by agents these days," Connors follows by saying, “That capability applies both to risk assessment before migration and to operationalizing the platform once it's live.”
Where AI Fits
Once the paved road is defined, an agent can use that definition as the baseline for everything it produces, no matter which direction a team takes it. The definition has to exist first, from a data perspective, because AI consumes that data and becomes an accelerator only once it has something reliable to work from. This is also why the platform underneath matters. Read our recent post, AI in the DevOps stack if interested in diving deeper into this topic.
Koza framed the tradeoff plainly during the session stating, “AI is great at doing the work. A little less great at judgment.”
Paved roads and clear ownership boundaries are what keep that gap from becoming a liability. Point AI at an undefined environment and it produces confident-sounding noise, a pattern Connors ties straight back to the early days of DevOps automation, stating that ill-defined workloads just move faster when AI touches them, not better, and the risk compounds in the AI world because the output is so persuasive. "It almost persuades the engineers that it's the right thing to do," he said.
How to Apply These Insights to Your Next EKS Migration
- Score every workload by its worst-case dimension, and treat the first cohort as a controlled experiment.
- Map foundational platform dependencies, identity, secrets, and network address space before building the onboarding roadmap, and put shared dependencies first regardless of which services are asking for features.
- Pressure-test the cutover model against statefulness, existing maintenance windows, and availability zone span before defaulting to a gradual, service-by-service playbook.
- Fix over-provisioning as a governance decision before layering FinOps tooling on top of an unoptimized baseline.
- Write down platform, workload, and service ownership boundaries before a consolidation effort forces the question under pressure.
- Define the paved road at the data layer first, so any AI agent introduced later inherits a reliable baseline.
Access the full EKS on Demand fireside chat here: EKS Modernization: What Do You Do First?
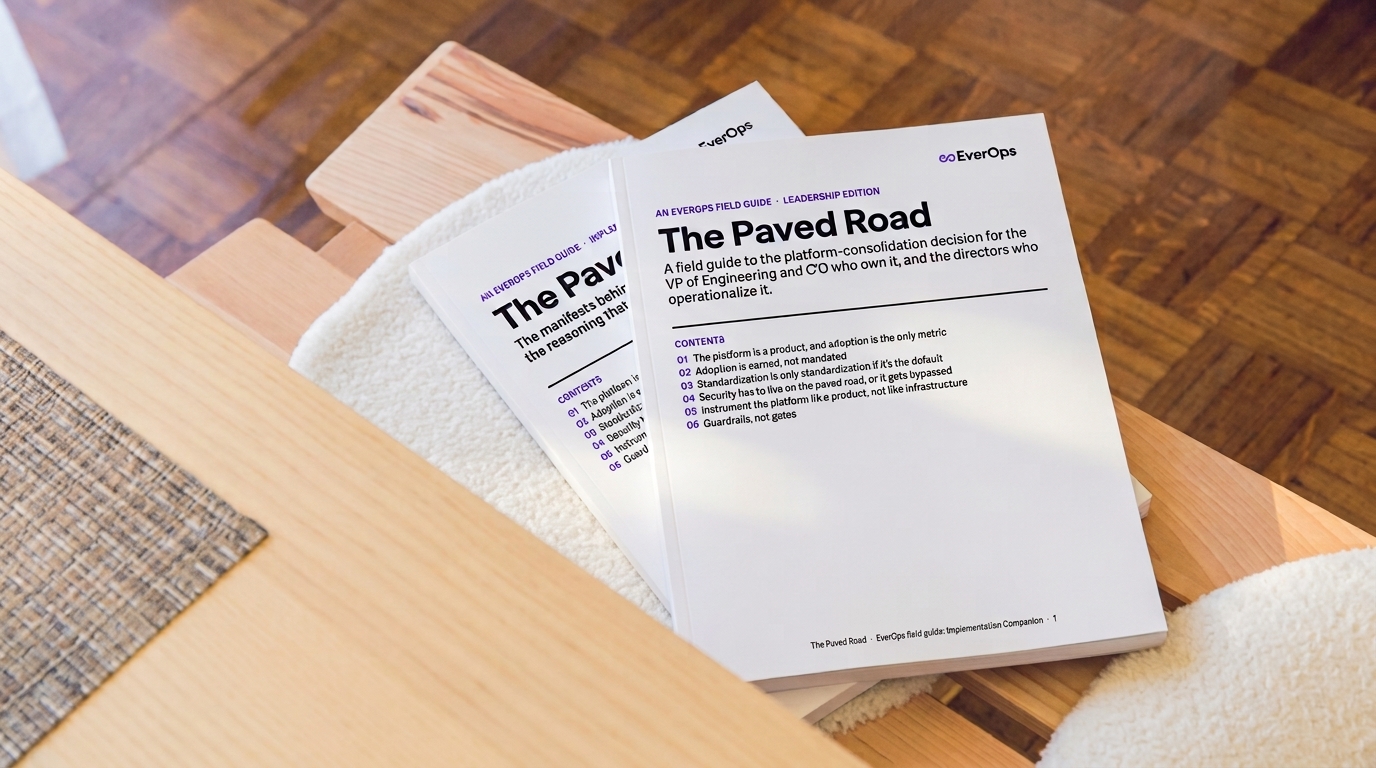
Want more? Access both editions of The Paved Road now. Either download them instantly or have them sent to your inbox, and see the consolidation model this sequencing work depends on, along with how a single platform absorbs every workload's cost and ownership decisions.
Map Your Sequence Before You Move with EverOps
This exclusive EKS on Demand session covered sequencing discipline, cost governance, ownership boundaries, and more, and serves as the foundation for the EKS Migration Readiness Assessment, which covers everything surrounding what to do before a single workload moves.
In just four weeks, the Assessment delivers a risk-mapped roadmap, a validated architecture, and a sequenced migration plan with rollback defined at every boundary. It stays grounded in your actual environment because the engineers who build the plan are the same engineers who execute it, so there is no handoff and no ramp-up between assessment and migration.
For more information, check out our recent post, An Inside Look at EverOps’ Newest EKS Migration Readiness Assessment, which covers what to expect when running inside your org and what happens next.
When you’re ready, reach out to our team to get a sequenced plan built around how your environment actually works.
Frequently Asked Questions
Where can I access the EKS on Demand fireside chat?
You can access the full session on demand here: EKS Modernization: What Do You Do First? It's a free, roughly 20-minute fireside chat between Stephen Koza (CEO, EverOps) and Mike Connors (Director of Agentic Services, EverOps), built for CTOs, VPs of Engineering, and Directors of Platform and Infrastructure working through a Kubernetes modernization that has to hold up in production.
How long does a well-sequenced EKS migration typically take?
Timelines vary with the number of workloads and how stateful they are, and a well-sequenced migration moves in deliberate phases. Foundational platform work and the first low-risk workloads typically take a few weeks, with the sequence expanding once the paved road proves itself. Teams that skip sequencing tend to spend that same time re-solving problems the first cohort already surfaced.
What is a paved road in the context of an EKS migration?
A paved road is the shared platform every workload migrates onto and develops against. It covers identity, networking, secrets, and cost policy in one consistent pattern. That replaces the patchwork of environment-specific configurations that usually grows when teams solve the same problems independently. Once it exists, every new workload inherits that baseline, and the team building it never starts from a blank cluster.
Get the latest resource from our team to see what we mean in practice: The Paved Road
Why does sequencing matter more than technical readiness?
Technical readiness answers whether a workload can run on EKS. Sequencing answers what a team learns from each migration and how much of that learning applies to the next one. Migrating the easiest service first can look efficient in the short term, but it skips the feedback loop that would have caught a foundational gap before a harder workload hit it.
Does FinOps tooling reduce EKS costs on its own?
Tooling reports where cost is going, but it doesn't change the scheduling and provisioning defaults that create the cost in the first place. EKS assigns resources based on what a workload's manifest requests, which is why you have to set a usage-based governance policy before layering on tooling. Teams that reverse the order end up with an accurate dashboard and the same overspend.
How does AI factor into an EKS migration?
AI works from whatever the platform hands it, so a well-defined paved road becomes the baseline an AI agent operates from. Once ownership and dependencies are documented, an agent can help assess migration risk and operationalize the platform once workloads land. Feeding AI an undefined environment produces confident output that is not necessarily accurate.
Who should be involved in scoring workloads before migration?
Scoring works best with input from the teams that own each workload's dependencies, data handling, and pipeline maturity, since those details rarely live in one place. Platform and infrastructure teams typically run the rubric, but service owners confirm the details that determine blast radius. Getting that input early keeps a workload from being scored as lower risk than it actually is.